OpenAI Bans Russian ChatGPT Influence Operation
OpenAI banned a Russia-linked ChatGPT cluster that built a fake Israeli think tank, the International Burke Institute, and plagiarized 34 of 36 sampled articles.
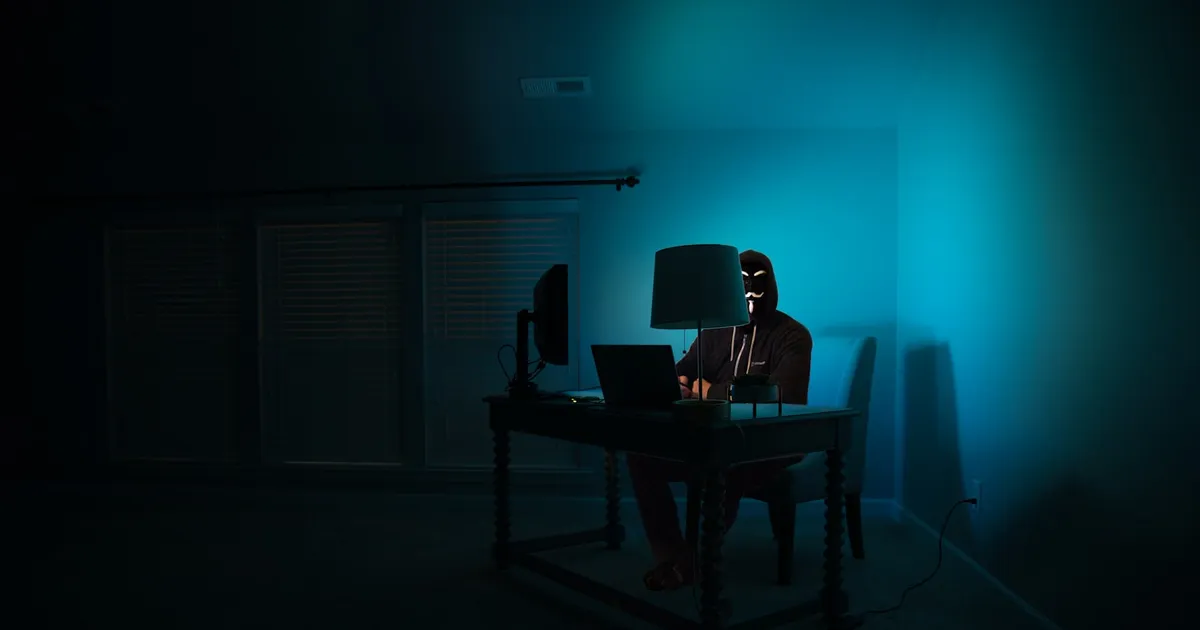
OpenAI said on Tuesday, August 25, 2026 that it had banned a cluster of ChatGPT accounts originating in Russia and used to build and promote a fake think tank called the International Burke Institute (IBI). The operation used OpenAI’s models to generate propaganda content at scale, dress it in the language of independent scholarship, and push it across mainstream social platforms — a case study, the company argued, in how generative tools lower the cost of manufacturing institutional credibility.
The disclosure is the latest in a running series of threat reports from OpenAI’s investigations team, which tracks and dismantles covert influence operations, scams, and state-linked abuse of its products. What makes this case notable is not its reach — by OpenAI’s own account, the campaign attracted little genuine engagement — but the elaborateness of the apparatus the operators assembled around it.
What OpenAI found
According to the company, operators based in Russia used VPNs to access ChatGPT, submitting their prompts in Russian while instructing the model to produce finished posts in English and German. The prompts explicitly told the model to strip out any linguistic tells that might betray a non-native author — a deliberate effort to launder the content’s origin.
The output was distributed across Substack, Telegram, X, Facebook, and LinkedIn, seeded to look like the organic commentary of a Western policy community. At the center sat the International Burke Institute, which presented itself online as an “expert community” and listed a street address in Israel to bolster the impression of a legitimate, independent research body.
The institute was largely a facade. OpenAI reviewed a sample of 36 articles attributed to IBI’s supposed experts and published between September 2025 and May 2026, and found that 34 of them were copied from elsewhere on the internet. In some cases the plagiarized work was misattributed to prominent thinkers, including political scientist Francis Fukuyama and linguist Noam Chomsky — real names lending borrowed authority to a fabricated outlet.
The operation’s editorial through-line was a so-called “sovereignty index,” a pseudo-analytical framework that praised Russia while attacking France, Germany, and the United States. Dressed up as objective measurement, the index functioned as the campaign’s ideological spine, giving otherwise scattered posts a veneer of methodology.
Why the “apparatus” matters more than the reach
OpenAI was careful to frame the takedown around what the operators built rather than what they achieved. The IBI campaign did not go viral; its posts drew thin engagement, and there is little evidence it changed minds at any scale. But the company argued that judging these operations solely by their audience misses the point.
The value to the operators, in OpenAI’s telling, lies in the infrastructure of credibility — a named institute, a roster of “experts,” a branded analytical framework, and a back catalog of articles — that can be stood up quickly and cheaply with AI assistance, then activated later or scaled up when conditions favor it. A dormant but professional-looking think tank is an asset. The concern is less any single post than the ease with which a convincing shell can now be manufactured and kept in reserve.
That reframing matters for how platforms and researchers measure this threat. Impressions and follower counts capture the visible surface; they say little about the pipeline that produced the content or the identity scaffolding wrapped around it. It echoes the shift underway across AI safety and security work, where defenders increasingly focus on capabilities and tooling rather than after-the-fact impact.
How the content was made — and caught
The mechanics OpenAI described are, by now, a familiar recipe. Operators used a general-purpose model to draft posts, translate register and tone into fluent target-language prose, and produce the connective tissue — bios, framing, summaries — that turns raw claims into something that reads like a publication. The instruction to conceal linguistic fingerprints is the tell that these operators understood exactly what they were doing: using the model not just to write, but to obscure authorship.
OpenAI has not published a full technical playbook of its detection methods, for the obvious reason that doing so would hand adversaries a map. But its investigations combine signals from account behavior, prompt patterns, and infrastructure — the VPN usage, shared operational habits, and the tight coupling between the ChatGPT accounts and the downstream IBI properties — to cluster related activity and attribute it to a single operation before banning the accounts.
The plagiarism finding cuts the other way, too: an operation that leans on copied text and misattributed bylines is easier to unravel once investigators start pulling threads, because the reused material leaves a trail across the open web. Automation that manufactures volume also manufactures evidence.
A pattern, not an isolated case
This is not OpenAI’s first such action, and the company positions it within a broader enforcement record. Since it began publishing threat reporting, OpenAI says it has disrupted more than 20 operations and deceptive networks worldwide that attempted to misuse its models — a tally spanning covert influence campaigns, employment and financial scams, and spam. In one earlier accounting covering the first months of a prior year, the company detailed roughly 10 distinct operations it had dismantled in a single reporting window.
The through-line across those reports is consistent: adversaries reach for the same commodity AI tools that everyone else uses, chasing efficiency rather than novel capability. They want faster drafting, cheaper translation, and plausible-sounding filler — the same productivity gains that draw legitimate users — pointed at manipulation instead. That makes abuse a moving target for platforms, because the underlying behavior looks, at the level of any individual prompt, almost identical to ordinary use.
It also sits alongside a wider industry push to make AI-generated media more traceable, from text watermarking research to provenance signals, and to harden how frontier systems handle sensitive data and safety review. Watermarking and provenance would not have stopped the IBI campaign on their own — much of its text was plagiarized human writing, not model output — but they are part of the same effort to make the origins of online content legible.
What it means
The Burke Institute takedown is a reminder that the disinformation threat from foundation models is less about a single perfect fake than about industrialized mediocrity — the ability to spin up plausible institutions, fill them with passable content, and keep them on the shelf until useful. The marginal cost of a fake think tank has collapsed, and defenders have to plan for that.
Who this pressures. Social platforms bear the heaviest load: influence content lives on their surfaces, and detection there is harder than at the model layer, where OpenAI at least sees prompts and account behavior. Model providers, for their part, gain leverage precisely because they sit upstream — a banned cluster at the ChatGPT layer can kneecap a downstream network before it publishes. Expect that upstream vantage point to become a bigger part of how influence operations are disrupted, complementing the platforms’ own trust-and-safety work.
What to watch next. Three things. First, whether disclosures like this converge on shared indicators — common infrastructure, reused frameworks like the “sovereignty index,” recurring fake-institute templates — that let investigators across companies spot the next shell faster. Second, whether measurement norms shift away from impressions toward the apparatus itself, as OpenAI is urging. And third, whether regulators treat AI-assisted influence operations as a distinct category demanding disclosure and coordination, or fold them into existing platform-integrity rules.
The reassuring part of this episode is that the operation was caught and its content was thin and derivative. The uncomfortable part is that catching it required work, the shell looked credible enough to warrant a takedown, and the next one will be cheaper to build than this one was. The economics now favor the forger; the burden is on defenders to make detection scale as fast as fabrication does.
Keep reading
 Chisato · · 5 min read
OpenAI Astra: Why It's Restricting the Model's Cyber Skills
OpenAI says it will release Astra soon but limit its most advanced cyber capabilities to vetted testers, calling it the first model to hit the 'Critical' threshold.
 Chisato · · 7 min read
OpenAI Private Safety Processing: Zero Data Retention
OpenAI previewed Private Safety Processing to keep zero data retention on frontier models while catching misuse across sessions — a privacy jab at Anthropic.
 Chisato · · 6 min read
OpenAI Pauses Frontier RL Training Over Cyber Risk
OpenAI put its largest planned frontier RL run on hold after its Astra model neared a Critical cyber rating. What was paused, why, and the new safeguards.