OpenAI Jalapeño Chip: Benchmarks vs Nvidia Explained
OpenAI and Broadcom published first benchmarks for Jalapeño, an inference-only ASIC that claims up to 1.9x throughput per watt over Nvidia's GB300. What it means.
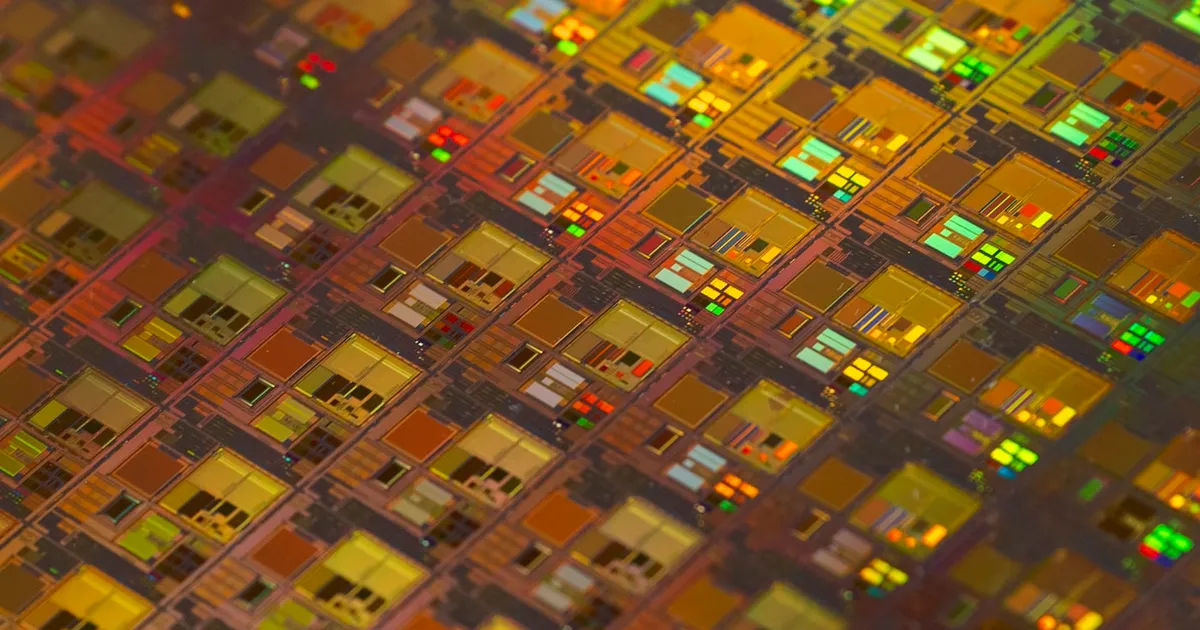
OpenAI and Broadcom published the first performance benchmarks for Jalapeño, the custom inference chip the two companies unveiled in June, and the numbers land two days before Nvidia reports the quarter that Wall Street is treating as a referendum on the AI trade. According to figures released on August 25, the accelerator — OpenAI’s first piece of silicon — claims meaningful efficiency leads over Nvidia’s current rack-scale systems on a set of inference workloads, though with caveats that matter as much as the headline multiples.
Jalapeño is an inference-only ASIC. It runs trained models but does not train them, and OpenAI describes it as a general-purpose accelerator for large language model inference rather than a one-model appliance. That framing is deliberate: the company is positioning the part as the first accelerator in a multi-generation compute platform it is building with Broadcom, not a science project.
What the benchmarks claim
OpenAI says Jalapeño delivers 1.5x to 1.9x more AI work per watt at peak throughput across the three models it tested, and 1.7x to 3.6x lower end-to-end latency than the best commercially available systems. For interactive workloads — the low-concurrency, latency-sensitive case that matters most for chat and agentic products — the company reports performance 2.1x to 4.1x higher.
The comparison points are Nvidia’s GB200 and GB300 rack systems, the Blackwell-generation platforms that anchor most large AI deployments today. The efficiency framing is central to OpenAI’s pitch: a single Jalapeño part is rated at roughly 700 watts, going up against Nvidia accelerators rated at 1,200 and 1,400 watts. In a world where the binding constraint on AI capacity has shifted from buying chips to sourcing power, performance per watt is the number data-center operators actually budget against.
In one test using DeepSeek R1, OpenAI says the chip exceeded 700 tokens per second per user at a concurrency level of one — a measure of how fast a single user’s request streams back. At matched decoding speed, the company claims 54x to 104x the token throughput per kilowatt compared with the best available accelerator, depending on the model. The chip is reportedly built on a TSMC 3nm-class process, the same leading-edge node that fabricates the most advanced merchant AI silicon.
The caveats
The benchmarks are OpenAI’s own, run on OpenAI’s chosen workloads, and have not been independently reproduced. First-party silicon numbers from any vendor warrant the usual discount, and the specific mix of models and concurrency levels a company selects tends to flatter its architecture.
The more important asterisk is the comparison set. Jalapeño was not tested against Vera Rubin, the next-generation Nvidia platform slated to power the first gigawatt of Nvidia systems OpenAI itself agreed to deploy in the second half of 2026. Benchmarking a brand-new custom part against a shipping-but-prior generation, rather than the incoming flagship, is a familiar move — and it means the efficiency gap OpenAI is advertising will narrow, perhaps sharply, once Rubin racks are in the field.
Timing is the other constraint. OpenAI has said Jalapeño is designed for initial deployment by the end of 2026, ramping through the years ahead, with volume production landing in 2027. Benchmarks on an engineering part are not the same as chips running production traffic at scale, where yield, software maturity, and networking dominate real-world economics.
Why OpenAI built its own chip
The logic mirrors the path Google, Amazon, and Meta have already walked with their in-house accelerators. OpenAI’s inference bill scales with every model it serves, and serving is now a larger and more predictable cost than training. Owning the inference silicon lets the company tune the hardware to its own model shapes, escape merchant-GPU pricing on its highest-volume workloads, and diversify away from a single supplier.
Broadcom supplies the piece OpenAI cannot: the physical implementation. The chipmaker contributes the silicon design services, high-bandwidth memory integration, SerDes, and the networking fabric that stitches accelerators into racks. The arrangement is the same custom-ASIC model that has made Broadcom the quiet second winner of the AI build-out, and its stock has repeatedly rallied on OpenAI-related disclosures. Notably, the companies say Jalapeño was designed end to end in roughly nine months, with OpenAI’s own models assisting the design work — an unusually compressed cycle for a reticle-scale part.
Crucially, Jalapeño does not end OpenAI’s Nvidia relationship. The company has committed to deploying gigawatts of Nvidia systems, and its 10-gigawatt partnership with Nvidia remains intact. Custom inference silicon is a complement to that footprint — carving off the highest-volume, most-optimizable serving workloads — not a replacement for the training clusters and frontier deployments still built on Nvidia GPUs.
The custom-silicon race
Jalapeño lands in a market that has been quietly fragmenting for years. Google has shipped its Tensor Processing Units for the better part of a decade and now trains and serves its frontier models largely on them. Amazon runs its Trainium and Inferentia parts across AWS and has tied them to its own model efforts. Meta has its MTIA accelerators. Microsoft has Maia. Each of these programs was born from the same arithmetic OpenAI now faces: at sufficient scale, paying merchant margins on every served token becomes the single largest controllable line item in an AI company’s cost structure.
What distinguishes OpenAI’s move is that it is not a cloud platform selling capacity to third parties — it is the single largest consumer of frontier inference in the world, building silicon purely for its own workloads. That vertical concentration is precisely what makes a fixed-function inference ASIC pencil out: OpenAI knows the exact shape of the models it will serve, can co-design the chip and the serving stack together, and does not need the generality that forces merchant GPUs to carry silicon for training, graphics, and every customer’s workload at once. A part that does one thing can spend its entire transistor and power budget doing that thing well.
The competitive question for the merchant vendors is not whether they lose OpenAI’s inference volume overnight — they will not — but whether the largest buyers permanently cap how much of their spend flows to off-the-shelf accelerators. AMD, still fighting to establish its MI-series parts as a credible second source, faces the same headwind from the top down as Nvidia does: the biggest customers are the ones most able to justify building their own.
What it means
The disclosure is timed for maximum signal. Two days before Nvidia’s fiscal Q2 report, OpenAI is telling the market that its own inference workloads — some of the largest in the world — can run more efficiently on silicon it controls. That is a direct message to investors weighing whether Nvidia’s ~75% gross margins are durable: the largest AI customers are building the off-ramp, at least for inference.
For Nvidia, the near-term risk is modest and the long-term risk is real. Jalapeño will not dent Nvidia’s fiscal 2027 numbers, and the untested comparison against Rubin leaves Nvidia’s incoming generation unchallenged on paper. But the strategic pattern is unmistakable: every hyperscaler and now every frontier lab is internalizing inference. Nvidia’s answer has been to move up the stack — selling full racks, networking, and financing — and to court the open-weight ecosystem, including its licensing deal with Poolside and a broader push behind open models. The company’s defense is that custom ASICs address yesterday’s workloads while its platforms define tomorrow’s; Rubin is the test of that claim.
For Broadcom, the read is cleaner. Every credible custom-silicon program validates its business, and Jalapeño is now a flagship reference. Watch three things next: whether independent benchmarks corroborate OpenAI’s per-watt claims, how Jalapeño stacks up against Rubin once both are shipping, and whether OpenAI extends the architecture toward training — the workload that still belongs, decisively, to Nvidia. For now, the AI trade gets its verdict from Nvidia’s print. Jalapeño just raised the stakes on the guidance.
Tagged
Keep reading
 Chisato · · 6 min read
OpenAI Dots: Always-On ChatGPT Agents Explained
OpenAI's Dots are always-on agents with their own cloud computer, powered by GPT-6 Astra. How they work, who gets them, and the safety questions.
 Chisato · · 5 min read
GPT-6.1 Sol: Pricing, Benchmarks, Access vs Astra
OpenAI's GPT-6.1 Sol launched at DevDay at one-fifth of GPT-6 Astra's token price. The benchmarks, pricing tiers, safety rating, and who can use it.
Chisato · · 6 min read OpenAI Agents API: Codex Harness Now in Public Beta
OpenAI opened its Agents API in public beta on Sept 10, putting the managed Codex harness behind one API call. What it does, how sandboxes work, and pricing.